
AI
Breaking AI announcements, model launches, company news
The lead
Latest first
Browse AI by topic
Open-Source AI
Hugging Face, GitHub, Ollama, local models, agent frameworks
Explore 55 postsModel Launches
Every AI model release that matters: benchmarks, context windows, pricing, and honest first takes.
Explore 43 postsAI Agents & MCP
Autonomous AI agent frameworks, multi-agent systems, and real deployments shipping today.
Explore 29 postsAI Use Cases
Real examples of what people are doing with AI
Explore 22 postsResearch
Peer-reviewed AI research distilled: what was proven, what it changes, and what it does not.
Explore 10 postsPolicy & Safety
AI legislation, safety frameworks, and court cases shaping how AI gets deployed.
Explore 1 postAI Tools
Curated directory of AI tools by category
Explore 1 postLocal AI
Local AI installs and private inference: Ollama, llama.cpp, and self-hosted setups.
ExploreLatest in AI
Aegis puts a trusted gate between AI agents and your tools
Researchers built Aegis, a runtime layer that approves or blocks each AI agent tool action and logged zero risky side effects across…
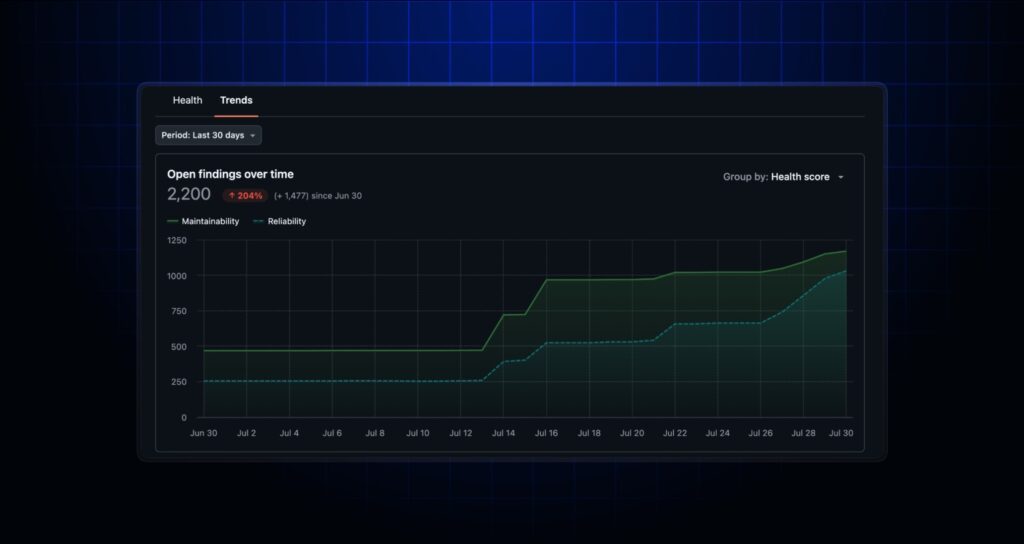
GitHub adds org-wide code quality trend tracking
GitHub's Code Quality dashboard now plots open findings over 7, 14, or 30 days and ranks repositories by improvement, so teams catch…
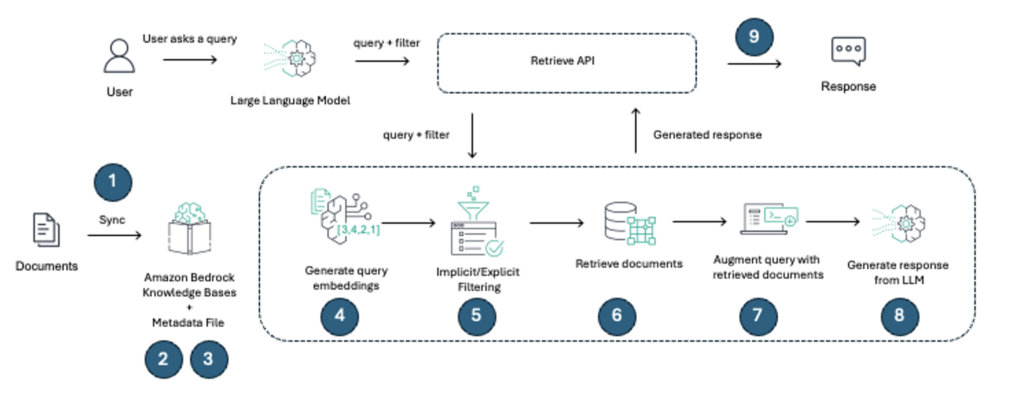
AWS adds smart filters to cut contract-search misses
Amazon Bedrock's AIDA adds metadata filters to contract search so legal teams surface the right clauses instead of near-misses, keeping a lawyer…
Apple study: when AI’s human tone misfires
Apple researchers analyzed 21,000 chats across four leading chatbots and found users draw a firm line on which human traits an AI…
Two centuries of botany parsed into 55,737 traits
The arXiv framework pairs rule-based parsers with LLM ensembles to turn centuries of botanical texts into 55,737 trait records across 4,961 species.
Plain prompts can’t reliably score shared decisions
Asking an LLM to judge shared decisions in pediatric surgery talks in one prompt fails; a small trained model scores higher, yet…
Safety benchmarks misfire on small language models
A study of five AI safety suites against 26 small language models found ambiguous scores that make leaderboard rankings mathematically fragile.
Unwritten benchmark breaks GPT-4o and Gemini
A new arXiv benchmark asks AI to read unwritten words from pen sounds and hand motion. Humans top 80%; GPT-4o and Gemini…
OpenAI and CodeAI launch AI literacy push for teens
OpenAI and CodeAI launched a teen AI literacy partnership with ChatGPT for Teens, as a survey finds most students use AI without…
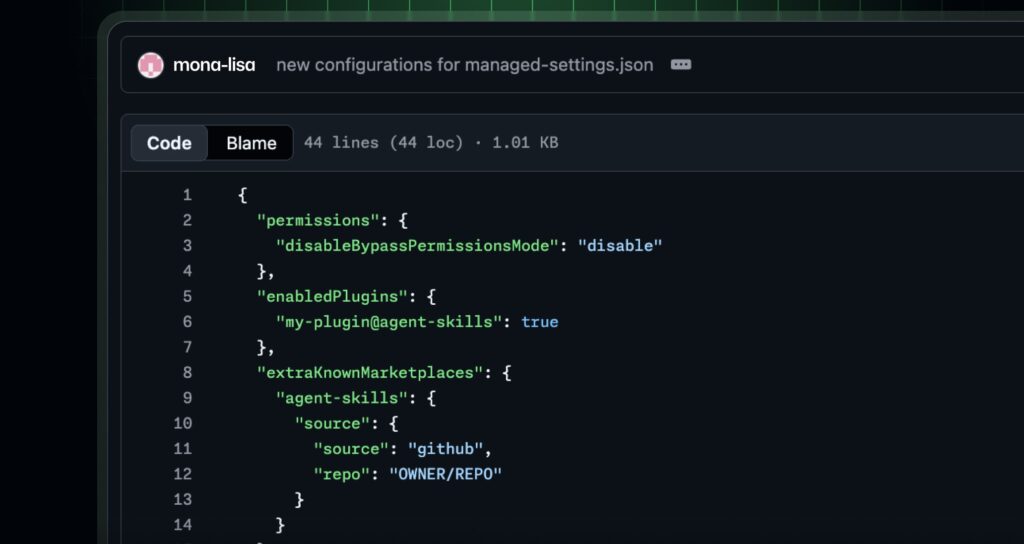
GitHub lets companies control Copilot inside JetBrains
GitHub now lets enterprise admins enforce Copilot plugin, MCP server, telemetry, and permission rules centrally in JetBrains IDEs, curbing unsanctioned AI tool…